Annotieren, Analysieren, Interpretieren und Visualisieren: In CATMA können Textwissenschaftler:innen so arbeiten, wie es ihren Fragestellungen am besten entspricht: qualitativ oder
Short description of the project
The long-term project funded by the NRW Academy of Sciences and Arts and the Union of German Academies at the University of Bonn explores the script and language of the Classic Maya culture. It aims to document Maya hieroglyphic inscriptions in a database and to catalog the hieroglyphic language in a digital dictionary. Sources such as literature, archives, and photo collections are researched, processed in the virtual research environment TextGrid, and published online. Information and images of inscriptions are stored in an object database and in the "Maya Image Archive," an open-access repository containing over 15,000 images, freely accessible to users.
Project content
The project "Text Database and Dictionary of Classical Maya" is dedicated to the study of Maya script and language. At its core is a machine-readable corpus based on XML/TEI, designed specifically for computer-assisted research and capable of continual updates and expansions. This flexible structure facilitates the incorporation of the latest research findings and the ongoing adaptation to current developments in script studies. The corpus includes a comprehensive inventory of all relevant script and language data, including undeciphered passages that are accurately represented in hieroglyphic form and annotated both temporally and spatially. Additionally, epigraphic and linguistic analyses are conducted, and cultural-historical commentaries as well as references to secondary literature are integrated. The digital capture of these texts enables detailed linguistic evaluations, such as concordance and collocation analyses, which aid in identifying text patterns.
A significant aspect of the project is the creation of a digital grapheme inventory of Maya script within TextGrid, currently comprising about 1,000 characters and nearly 1,500 character variants, of which just over half are securely deciphered through linguistic analyses. Due to the complex nature of Maya hieroglyphs and unlike similar projects in Egyptology or cuneiform studies, it is not feasible to capture the hieroglyph texts in phonemic transliterated values. Instead, a numerical transliteration of the texts is performed using character numbers based on the digital character catalog.
To convert these numerically encoded texts into readable documents, a linguistic annotation tool was developed. This tool, created in collaboration with Dr. Cristina Vertan and named ALMAH ("Annotator for the Linguistic Analysis of Maya Hieroglyphs"), utilizes the transliteration values stored in the character catalog to create a semi-automatic phonemic transliteration of the texts. These transliterations are then manually refined and form the basis for the comprehensive Dictionary of Classical Maya, thus contributing to the scientific and cultural elucidation of this ancient language.
Add your DH research project to the project showcase by submitting a short project description via the web form. Enter project data, a brief description, a graphic or visualization as well as a detailed description of the project content with technical assignment, addressees, added value, project managers, funding information and duration.

Annotieren, Analysieren, Interpretieren und Visualisieren: In CATMA können Textwissenschaftler:innen so arbeiten, wie es ihren Fragestellungen am besten entspricht: qualitativ oder
DARIAH-DE (gefördert 2011-2019) unterstützt die mit digitalen Ressourcen und Methoden arbeitenden Geistes- und Kulturwissenschaftler/innen in Forschung und Lehre. Dazu baut
Digital edition of the economic-technological encyclopaedia by J. G. Krünitz, published in 242 volumes from 1773 to 1858.
Die digitale Arbeitsumgebung ediarum ist eine aus mehreren Softwarekomponenten bestehende Lösung, die es Wissenschaftler*innen erlaubt, Transkriptionen von Manuskripten und Drucken
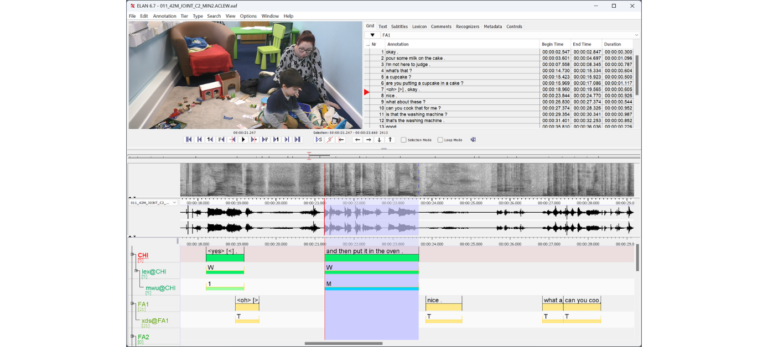
ELAN wird am Max-Planck-Institut für Psycholinguistik im Sprach-Archiv (TLA – The Language Archive) entwickelt. Es wird in der Programmiersprache Java
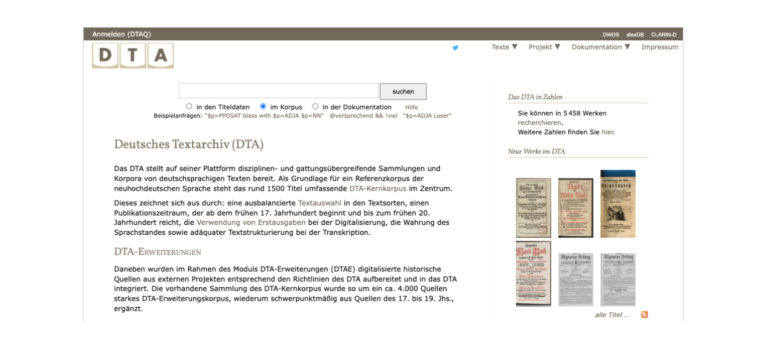
Das DTA ist ein Archiv für deutschsprachige, historische Textsammlungen an der Berlin-Brandenburgischen Akademie der Wissenschaften. Es umfasst annotierte Volltexttranskriptionen von
Die drei von Text+ adressierten Datendomänen Sammlungen, lexikalische Ressourcen und Editionen gehören zu den klassischen Feldern geisteswissenschaftlicher Forschung. Das Plus-Zeichen
The DARIAH-DE Geo-Browser enables a comparative visualization of several queries and supports the display of data and their visualization in a correlation of geographical spatial relationships at corresponding points in time and sequences. This allows researchers to analyze space-time relations of data and source collections and at the same time establish correlations between them.
Wir verwenden Cookies und ähnliche Funktionen zur Verarbeitung von Daten. Die Zustimmung ist freiwillig und kann jederzeit widerrufen werden.